LLM on Mac / Model
FLUX.2 [klein] 4B
distilled / BF16 or app-supported quantization
24 GB
For trying short tasks one at a time
A planning budget starting from the official ~13GB VRAM figure, with room for the text encoder, app and OS. Try one image at around 1024px. Format and app change actual usage.
Tasks to try
Prototype article illustrations, backgrounds and reference-guided edits. Generate one image at a time to refine composition.
Keep under review
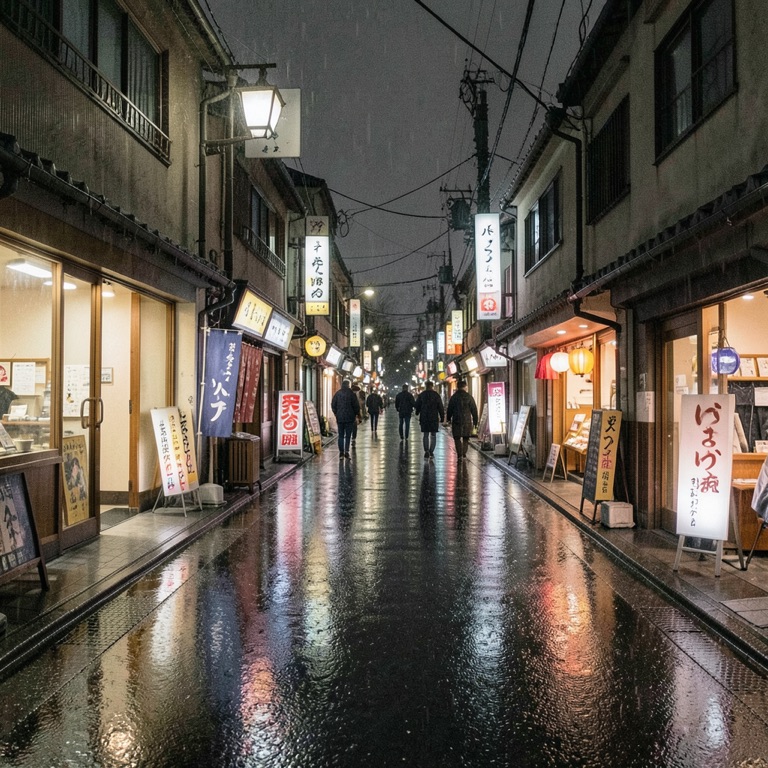
Check exact Japanese text, logos and identity consistency separately. Adding text afterward may be more dependable.
Getting started
Memory figures are editorial budgets including room for the OS and apps, not verified minimums. Text models assume 4-bit weights, 4K–8K input tokens and one model at a time. Long documents, images and concurrent apps need more. A3B does not mean the entire model fits in 3GB.
Assumes an Apple Silicon Mac and a compatible app: LM Studio or similar for text, Whisper apps for audio, and model-specific image/video tools. RAM alone does not determine speed. Start with a short input on your current Mac.
Measurements for this model
Timing is for subsequent images; memory is the backend-reported peak. This test used 8-bit weights. It does not establish identical conditions or requirements for every format in the guide.
Test conditions
{
  "width": 1024,
  "height": 1024,
  "seeds": [
    1,
    2
  ],
  "mlx_cache_limit_gb": 2,
  "quantization": "8bit",
  "runtime": "v0.20.0"
}
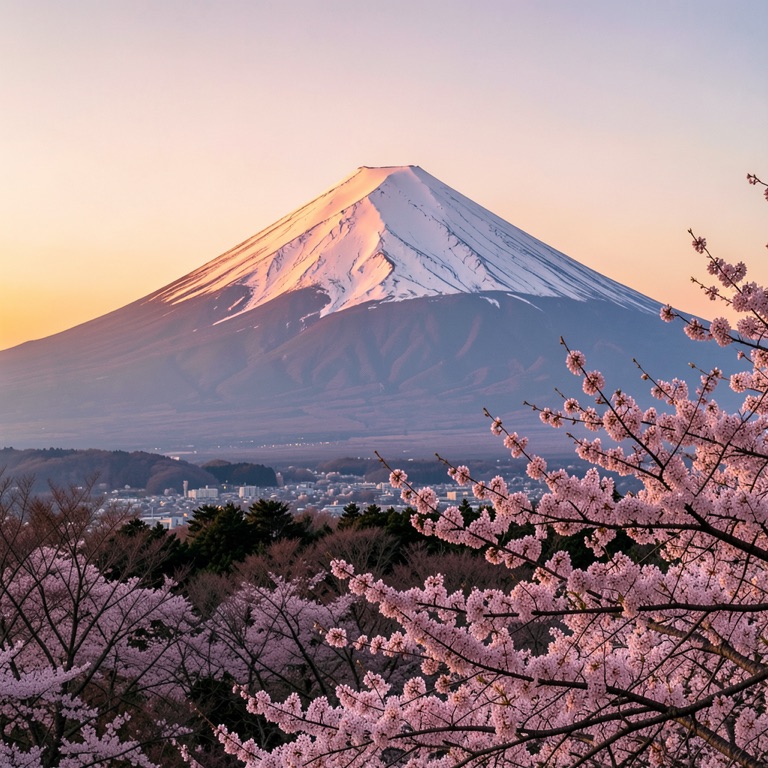
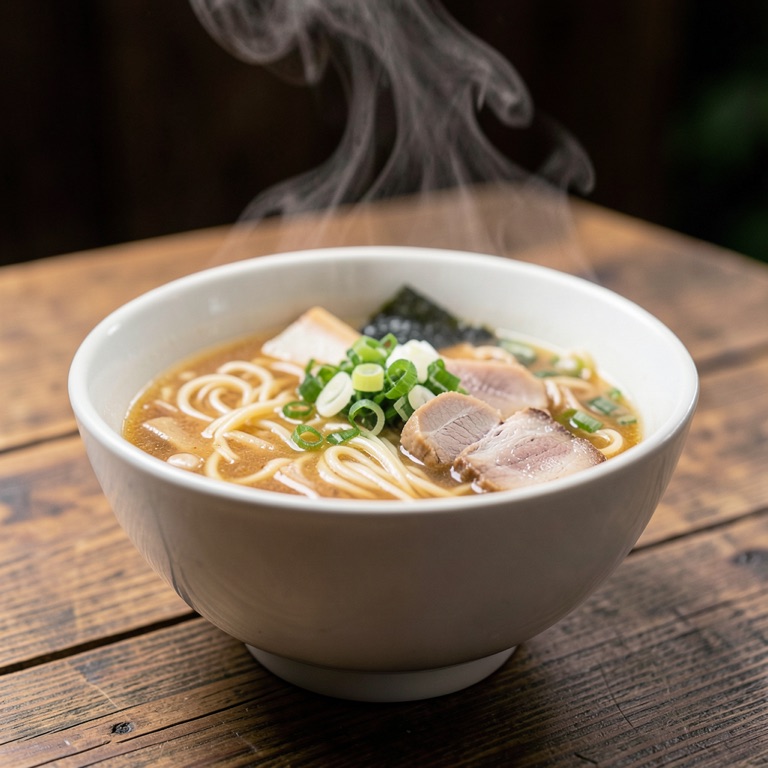
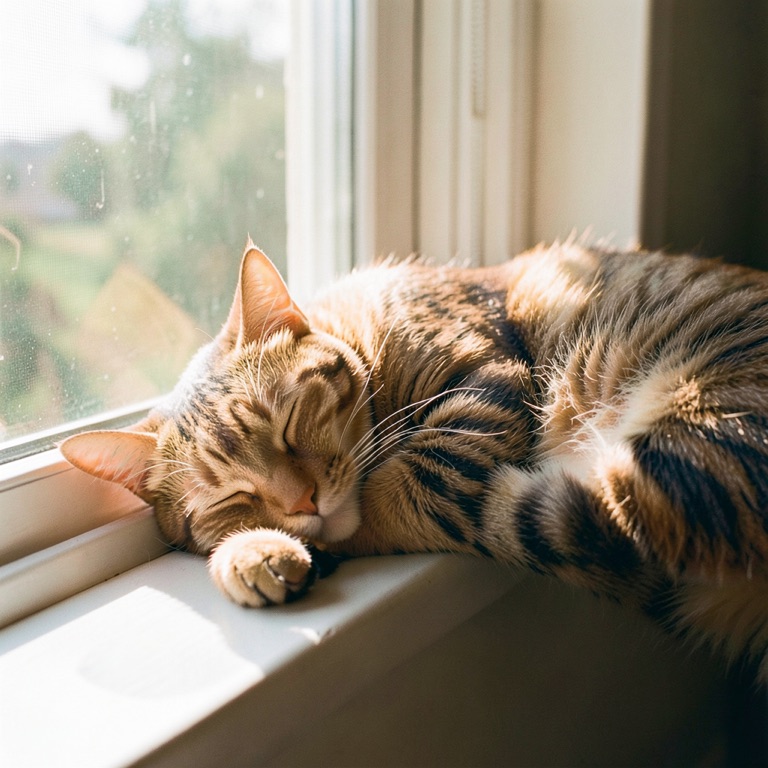
Generated examples